Wednesday, February 3, 2016

How Java garbage collection works

As a Java developer, we all know JVM provides us an automatic Garbage Collection mechanism. And we don't need to worry about memory allocation and deallocation like in C. But how GC works behind the scene? It would help us to write much better Java applications if we understand that.

There are many articles you can find from Google to dive deep into it, I will only put some GC basics in this blog. Firstly, you might heard a term of "stop-the-world". What does that mean? It means the JVM stops running the application for a GC execution.  During the stop-the-world time, every thread will stop their tasks until the GC thread complete its task.

JVM Generations

In Java, we don't explicitly allocate and deallocate memory in the code. The GC finds those unreferenced objects and removes them. According to an article by Sangmin Lee[1], the GC was designed by following the two hypotheses below.
  • Most objects soon become unreachable.
  • References from old objects to young objects only exist in small numbers.
Therefore, the memory heap is broken into different segments, Java calls them as generations.

Young Generation: All new objects are allocated in Young Generation. When this area is full, GC removes unreachable objects from it. This is called "minor garbage collection" or "minor GC".

Old Generation: When objects survived from Young Generation, they are moved to Old Generation or Tenured Generation. Old Generation has bigger size and GC removes objects less frequently from it. When GC removes objects from Old Generation, it is called "major garbage collection" or "major GC".

Permanent Generation: Permanent Generation contains metadata of classes and methods, so it is also known as "method area". It does not store objects survived from Old Generation. The GC occurs in this area is also considered as "major GC". Some places call a GC as "full GC" if it performs on Permanent Generation.

You may notice the Young Generation is divided into a Eden space and two Survivor Spaces. They are used to determine the age of objects and whether to move them to Old Generation.

Generational Garbage Collection

Now, how does the GC process with those different generations in memory heap?
1. New created objects are allocated in Eden space. Two Survivor spaces are empty at the beginning.


2. When Eden space is full, a minor GC occurs. It deletes all unreferenced objects from Eden space and moves referenced objects to the first survivor space (S0). So the Eden space will be empty and new objects can be allocated to it.
3. When Eden space is full again, another minor GC occurs. It deletes all unreferenced objects from Eden space and moves referenced objects. But this time, referenced objects are moved to the second survivor space (S1). In addition, referenced objects in the first survivor space (S0) also get moved to S1 and have their age incremented. Unreferenced objects in S0 also get deleted. So we always have one survivor space empty.
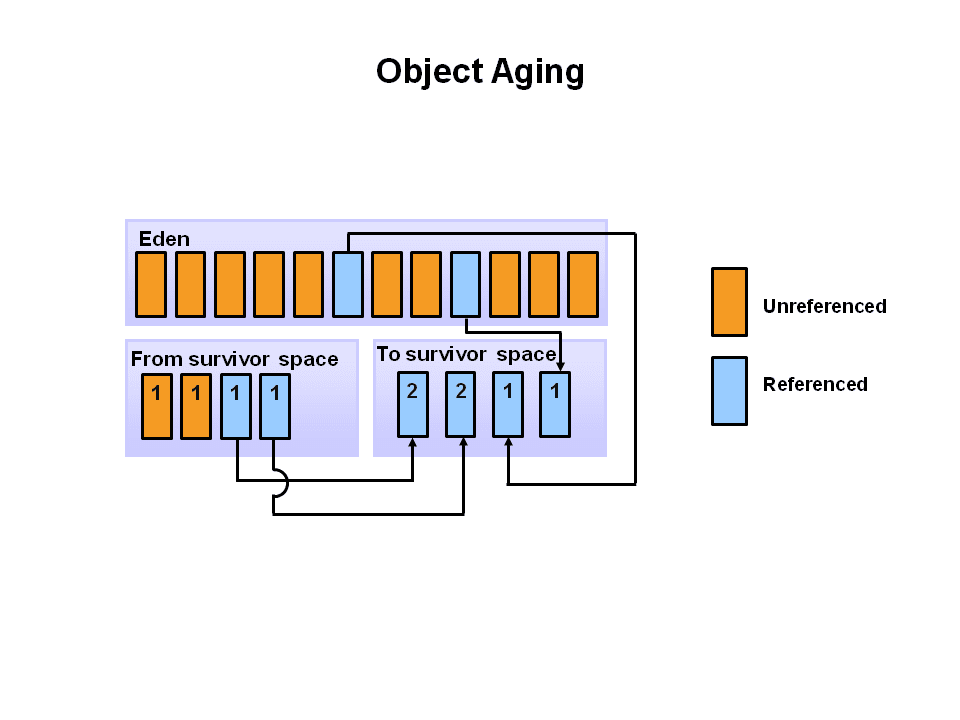
4. The same process repeats in subsequent minor GC with survivor spaces switched.
5. When the aged objects in survivor spaces reach a threshold, they are moved to Old Generation.
6. When the Old Generation is full, a major GC will be performed to delete the unreferenced objects in Old Generation and compact the referenced objects.

The above steps are a quick overview of the GC in the Young Generation. The major GC process is different among different GC types. Basically, there are 5 GC types.
1. Serial GC
2. Parallel GC
3. Parallel Compacting GC
4. CMS GC
5. G1 GC

The 5 GC types can be switched using different command lines, like -XX:+UseG1GC will set the GC type to G1 GC.

Monitor Java Garbage Collection

There are several ways to monitor GC. I will list some most commonly used ones below.

jstat

jstat is in $JAVA_HOME/bin. You can run it by "jstat -gc <vmid> 1000". vmid is the virtual machine identifier. It is normally the process id of the JVM. 1000 means display the GC data every 1 second. The meaning of the output columns can be found here.

VisualVM

Visual VM is a GUI tool provided by Oracle. It can be downloaded from here.

GarbageCollectorMXBean and GarbageCollectionNotificationInfo

GarbageCollectorMXBean and GarbageCollectionNotificationInfo can be used to collect GC data in a programming way. An example can be found from here in my GitHub. You can use "mvn jetty:run" to start a jetty server and observe the GC information like below.
Minor GC: - 61 (Allocation Failure) start: 2016-02-03 22:22:17.784, end: 2016-02-03 22:22:17.789
        [Eden Space] init:4416K; used:19.2%(13440K) -> 0.0%(0K); committed: 19.2%(13440K) -> 19.2%(13440K)
        [Code Cache] init:160K; used:14.7%(4823K) -> 14.7%(4823K); committed: 14.7%(4832K) -> 14.7%(4832K)
        [Survivor Space] init:512K; used:16.7%(1456K) -> 13.3%(1162K); committed: 19.1%(1664K) -> 19.1%(1664K)
        [Metaspace] init:0K; used:19393K -> 19393K); committed: 19840K -> 19840K)
        [Tenured Gen] init:10944K; used:18.6%(32621K) -> 19.2%(33563K); committed: 19.0%(33360K) -> 19.2%(33616K)
duration:5ms, throughput:99.9%, collection count:61, collection time:213

Major GC: - 6 (Allocation Failure) start: 2016-02-03 22:22:17.789, end: 2016-02-03 22:22:17.839
        [Eden Space] init:4416K; used:0.0%(0K) -> 0.0%(0K); committed: 19.2%(13440K) -> 19.2%(13440K)
        [Code Cache] init:160K; used:14.7%(4823K) -> 14.7%(4823K); committed: 14.7%(4832K) -> 14.7%(4832K)
        [Survivor Space] init:512K; used:13.3%(1162K) -> 0.0%(0K); committed: 19.1%(1664K) -> 19.1%(1664K)
        [Metaspace] init:0K; used:19393K -> 19393K); committed: 19840K -> 19840K)
        [Tenured Gen] init:10944K; used:19.2%(33563K) -> 14.0%(24559K); committed: 19.2%(33616K) -> 19.2%(33616K)
duration:50ms, throughput:99.6%, collection count:6, collection time:228

Or you can run the GCMonitor class as a java application. It would take long time to finish the execution until a major GC occurs.

Reference:
[1] http://www.cubrid.org/blog/dev-platform/understanding-java-garbage-collection/
[2] http://www.oracle.com/webfolder/technetwork/tutorials/obe/java/gc01/index.html

Sunday, October 18, 2015

Jackson serialization of Map Polymorphism with Spring MVC

I come across a problem of serializing Map type objects polymorphism when I re-engineering a legacy code. Spring MVC and Jackson are used in the RESTful API implementation. The problem is I have a list of Map type objects and they are in different implementation of Map. I want to serialize and deserialize the list with the actual type of each Map instance. For example, I have a list of map as below. One map is a HashMap and the other map is Hashtable.


List<Map> maps = new LinkedList<>();

Map<String, String> map1 = new HashMap();
Map<String, String> map2 = new Hashtable();

maps.add(map1);
maps.add(map2);

With Jackson's default settings, the type information of map1 and map2 will be lost after serialization. And they both will be LinkedHashMap after deserialization which makes sense to Jackson because it doesn't know the actual type of map1 and map2 in deserilaization. Jackson does provide a @JsonTypeInfo annotation to resolve the polymorphism problem, but it only applies to the values of the map, not the map itself.


After several days search online, the best solution I found so far is to customize the TypeResolverBuilder class used by Jackson's ObjectMapper instance. However, it requires both server and client side to set the customized TypeResolverBuilder to the ObjectMapper instance, which means if your RESTful API is exposed to the public, you have to provide your clients with the customized ObjectMapper class. I know it is not ideal, so if you have a better solution, please let me know. 

Now, the solution!

Firstly, write our own TypeResolverBuilder class. The important part is the useForType method. We override the method to return true if the type is a map like type.


public class MapTypeIdResolverBuilder extends StdTypeResolverBuilder {

    public MapTypeIdResolverBuilder() {
    }

    @Override
    public TypeDeserializer buildTypeDeserializer(DeserializationConfig config,
                                                  JavaType baseType, Collection<NamedType> subtypes) {
        return useForType(baseType) ? super.buildTypeDeserializer(config, baseType, subtypes) : null;
    }

    @Override
    public TypeSerializer buildTypeSerializer(SerializationConfig config,
                                              JavaType baseType, Collection<namedtype> subtypes) {
        return useForType(baseType) ? super.buildTypeSerializer(config, baseType, subtypes) : null;
    }

    /**
     * Method called to check if the default type handler should be
     * used for given type.
     * Note: "natural types" (String, Boolean, Integer, Double) will never
     * use typing; that is both due to them being concrete and final,
     * and since actual serializers and deserializers will also ignore any
     * attempts to enforce typing.
     */
    public boolean useForType(JavaType t) {
        return t.isMapLikeType() || t.isJavaLangObject();
    }
}


Then, we need to set it to the ObjectMapper instance used by Jackson. We will also have to call init and inclusion methods, otherwise exceptions will be thrown at runtime. It is not required to use JsonTypeInfo.Id.CLASS and JsonTypeInfo.As.PROPERTY, you can use whatever you want provided by JsonTypeInfo annotation.

ObjectMapper objectMapper = new ObjectMapper();
MapTypeIdResolverBuilder mapResolverBuilder = new MapTypeIdResolverBuilder();
mapResolverBuilder.init(JsonTypeInfo.Id.CLASS, null);
mapResolverBuilder.inclusion(JsonTypeInfo.As.PROPERTY);
objectMapper.setDefaultTyping(mapResolverBuilder);


As I said earlier, both client side and server side of our RESTful API need to use the above ObjectMapper instance to do the serialization and deserialization. Because I am using Spring MVC. So I have to register the ObjectMapper instance to the MappingJackson2HttpMessageConverter used by Spring. If you are using a different framework with Jackson, it should provide a way to set the customized ObjectMapper instance, hopefully. 

I will use the Java config instead of XML config in Spring. If you are using XML config, you can set the customized ObjectMapper instance as below, but it would be a bit tricky of how to call the init and inclusion methods in the ObjectMapper bean.

<mvc:annotation-driven>
        <mvc:message-converters>
            <bean class="org.springframework.http.converter.json.MappingJackson2HttpMessageConverter">
                <property name="objectMapper" ref="customObjectMapper"/>
            </bean>
        </mvc:message-converters>
</mvc:annotation-drive>


The Java config I am using at server side is as below.

@Configuration
@EnableWebMvc
@ComponentScan("com.geekspearls.mvc.jackson.server")
public class AppConfig extends WebMvcConfigurerAdapter {

    @Override
    public void configureDefaultServletHandling(DefaultServletHandlerConfigurer configurer) {
        configurer.enable();
    }

    @Override
    public void configureMessageConverters(List<HttpMessageConverter<?>> converters) {
        converters.add(converter());
    }

    @Bean
    public MappingJackson2HttpMessageConverter converter() {
        MappingJackson2HttpMessageConverter converter = new MappingJackson2HttpMessageConverter();
        converter.setObjectMapper(objectMapper());
        return converter;
    }

    @Bean
    public ObjectMapper objectMapper() {
        ObjectMapper objectMapper = new ObjectMapper();
        MapTypeIdResolverBuilder mapResolverBuilder = new MapTypeIdResolverBuilder();
        mapResolverBuilder.init(JsonTypeInfo.Id.CLASS, null);
        mapResolverBuilder.inclusion(JsonTypeInfo.As.PROPERTY);
        objectMapper.setDefaultTyping(mapResolverBuilder);
        return objectMapper;
    }
}


Then the client side class is as below. I am using the RestTemplate to call the RESTful service for simplicity.

public class ServiceConsumer {

    private static final String REST_ENDPOINT = "http://localhost:8080/rest/api";

    public InStock getInStock() {

        ObjectMapper objectMapper = new ObjectMapper();
        MapTypeIdResolverBuilder mapResolverBuilder = new MapTypeIdResolverBuilder();
        mapResolverBuilder.init(JsonTypeInfo.Id.CLASS, null);
        mapResolverBuilder.inclusion(JsonTypeInfo.As.PROPERTY);
        objectMapper.setDefaultTyping(mapResolverBuilder);

        List<HttpMessageConverter<?>> converters = new ArrayList<>();
        MappingJackson2HttpMessageConverter jackson2HttpMessageConverter = new MappingJackson2HttpMessageConverter();
        jackson2HttpMessageConverter.setObjectMapper(objectMapper);
        converters.add(jackson2HttpMessageConverter);
        RestOperations operations = new RestTemplate(converters);
        InStock s = operations.getForObject(REST_ENDPOINT + "/book/in_stock", InStock.class);
        return s;
    }
}


The complete code example can be found in my GitHub in the mvc.jackson package. The example can be run in jetty server via 'mvn jetty:run' command. And you will get the following JSON message when hit the server with URL 'http://localhost:8080/rest/api/book/in_stock in the browser. As you can see, it contains the type information of the maps `"@class": "java.util.Hashtable"` and `"@class": "java.util.HashMap"`.

{
  "store": "Los Angeles Store",
  "books": [
    {
      "@class": "com.geekspearls.mvc.jackson.server.model.ChildrenBook",
      "title": "Giraffes Can't Dance",
      "isbn": "1-84356-568-3",
      "properties": {
        "@class": "java.util.Hashtable",
        "Price": [
          "java.lang.Float",
          4.42
        ],
        "Type": "Board book",
        "Currency": "USD",
        "Pages": 10
      },
      "minAge": 3,
      "maxAge": 0
    },
    {
      "@class": "com.geekspearls.mvc.jackson.server.model.TextBook",
      "title": "Database Systems",
      "isbn": "1-84356-028-3",
      "properties": {
        "@class": "java.util.HashMap",
        "Pages": 560,
        "Type": "HardCover",
        "Price": [
          "java.lang.Float",
          146.16
        ],
        "Currency": "USD"
      },
      "subject": "Computer Science"
    }
  ]
}


By running the RestTest unit test provided in the example, you will get the following result. The first properties map is in Hashtable type and the second one is in HashMap type.

Store ->Los Angeles Store
book@com.geekspearls.mvc.jackson.server.model.ChildrenBook
Title: Giraffes Can't Dance
ISBN: 1-84356-568-3
Properties@java.util.Hashtable
Price -> 4.42@java.lang.Float
Currency -> USD@java.lang.String
Type -> Board book@java.lang.String
Pages -> 10@java.lang.Integer
Min Age: 0
Max Age: 3
=======================================
book@com.geekspearls.mvc.jackson.server.model.TextBook
Title: Database Systems
ISBN: 1-84356-028-3
Properties@java.util.HashMap
Pages -> 560@java.lang.Integer
Type -> HardCover@java.lang.String
Price -> 146.16@java.lang.Float
Currency -> USD@java.lang.String
Subject: Computer Science
=======================================

Saturday, August 29, 2015

Dynamic programming - The Longest Common Subsequence Problem

The longest common subsequence problem is a simple problem that illustrates dynamic programming.

Longest Common Subsequence Problem

The problem is given two strings A and B of length m and n respectively, determine the length of the longest subsequence that is common in A and B. For example, A = xyxzx and B = zxyzy, then the longest common subsequence of A and B is xyz and the length is 3.

Brute-force Method

One way to solve the problem is to enumerate all the \(2^m\) subsequences of A, and for each subsequence check if it is also a subsequence in B. The time complexity of this method is \(\Theta(n2^m)\).

Dynamic Programming Method

Another way to solve this problem is using dynamic programming. It is easy to observe the formula below. \(a_i\) is the character at index i in A. \(b_j\) is the character at index j in B. L[i, j] is the length of the longest common subsequence in the substring of A[0..i] and the substring of B[0..j]. 
  • If \(a_i = b_j\), L[i, j] = L[i - 1, j - 1] + 1.
  • If \(a_i \neq b_j\), L[i, j] = max{L[i, j - 1], L[i - 1, j]}.
For example, A = xyxzx, B = zxyzy. Consider substring of A[0..2] = xyx and substring of B[0..2] = zxy. The L[2, 2] = 2 and the longest common subsequence is xy. Then consider A[0..3] = xyxz and B[0..3]=zxyz. Because \(a_3\) = z == \(b_3\) = z, it is clear that the L[3, 3] = 3 = L[2, 2] + 1 and the longest common subsequence is xyz. Then let's consider  A[0..3] = xyxz and B[0..4] = zxyzy. Because \(a_3\) = z \(\neq\) \(b_4\) = y, the longest common subsequence should still be xyz and the L[3, 4] = L[3, 3] = 3.

We can use an (m + 1) \(\times\) (n + 1) table to store the values of L[i, j]. And we fill the table row by row using the above observation. Then L[m, n] has the length of the longest common subsequence in A and B. The pseudo code is described in LCS.

Algorithm 6 LCS
Input: Two strings A and B of length m and n respectively.
Output: The length of the longest common subsequence of A and B.
  1. for i = 0 to m
  2.     for j = 0 to n
  3.         if (i == 0 and j == 0) then L[i, j] = 0
  4.         else if (\(a_i\) == \(b_j\)) then L[i, j] = L[i - 1, j - 1] + 1
  5.         else L[i, j] = max{L[i, j - 1], L[i - 1, j]}
  6.         end if
  7.     end for
  8. end for
  9. return L[m, n]
A JAVA implementation of this algorithm can be found on GitHub LCS.

An Example

Running LCS algorithm with input A = "abcdeabcd" and B = "acebde" will generate the table below. The result is 5 and the longest common subsequence is "acebd".

       a  c  e  b  d  e
  [0, 0, 0, 0, 0, 0, 0]
a[0, 1, 1, 1, 1, 1, 1]
b[0, 1, 1, 1, 2, 2, 2]
c[0, 1, 2, 2, 2, 2, 2]
d[0, 1, 2, 2, 2, 3, 3]
e[0, 1, 2, 3, 3, 3, 4]
a[0, 1, 2, 3, 3, 3, 4]
b[0, 1, 2, 3, 4, 4, 4]
c[0, 1, 2, 3, 4, 4, 4]
d[0, 1, 2, 3, 4, 5, 5]


Time Complexity

Filling each entry in the table requires \(\Theta(1)\) time. The size of the table is \(\Theta(mn)\), so the time complexity of LCS algorithm is \(\Theta(mn)\), which is the total time of filling the whole table.

Sunday, August 16, 2015

Spring + Quartz integration example (3) - inject Spring bean into Quartz job instance

In my work of integrating Quartz scheduler with Spring. There is a requirement to pass an object into the Quartz job instance. The object is a Spring bean. I found because the Quartz job instance is created by Quartz thread and it doesn't aware of Spring context, so I couldn't use the Spring bean in the job class directly, it is always null. After googling it a bit, I found three ways to do that. 1. Pass the object into JobDataMap, 2. get it from Spring application context and 3. use Spring to inject the object. Personally, I vote for the third way as the best practice.


1. Passing the object into JobDataMap

This is the easiest way, what we have to do is letting our class implement Serializeble interface. Then the object can be simply passed into the Quartz JobDataMap. However, there is a flaw in this method. If you use a persistent JobStore, the object in it will be serialized. And you will get a class-versioning error if your class definition is changed in future. Quartz recommends only pass primitive and String into JobDataMap. For details, see Quartz lesson 3.

Put object into JobDataMap

   <bean id="object" class="com.package.MyObject"/>  
   <bean class="org.springframework.scheduling.quartz.JobDetailFactoryBean">  
     <property name="jobClass" value="com.package.MyJob"/>  
     <property name="jobDataAsMap">  
       <map>  
         <entry key="myObject" value-ref="object"/>  
       </map>  
     </property>  
     <property name="durability" value="true"/>  
   </bean>

Retrieve object in Quartz job class

...
MyObject obj = jobExecutionContext.getMergedJobDataMap().getString("myObject");
...
>

2. Using Spring application context

In this way, we have to define an application context key in the scheduler bean.
<bean id="scheduler"  
      class="org.springframework.scheduling.quartz.SchedulerFactoryBean">  
     <property name="applicationContextSchedulerContextKey" value="applicationContext"/>  
     <property name="jobDetails">  
       <list>
          ...  
       </list>  
     </property>  
     <property name="triggers">  
       <list>
         ...  
       </list>  
     </property>  
   </bean>
Then in the job class, we can get the Spring application context as below and retrieve any bean via the bean name.
try {
            ApplicationContext context =
                    (ApplicationContext) jobExecutionContext.getScheduler().getContext().get("applicationContext");
            if (context != null) {
                InjectObject obj = (InjectObject) context.getBean("geeksPearls");
                if (obj != null) {
                    System.out.println("[" + new Date() + "] I am saying hello from a Quartz job, " + obj);
                }
            }
        } catch (SchedulerException e) {
            e.printStackTrace();
        }
The completed example can be found on my GitHub Example3. Have a look at InjectTask class and the Spring context XML.


3. Using Spring injection

We can also use Spring injection to inject any object into our job. However, we have to do a bit more work. I found this way in this blog. And I think it's elegant and the Spring guys should use it as the default way.

Firstly, extend the SpringBeanJobFactory class as below.
public class AutowiringSpringBeanJobFactory extends SpringBeanJobFactory implements ApplicationContextAware {

    private transient AutowireCapableBeanFactory beanFactory;

    public void setApplicationContext(final ApplicationContext applicationContext) throws BeansException {
        beanFactory = applicationContext.getAutowireCapableBeanFactory();
    }

    @Override
    protected Object createJobInstance(final TriggerFiredBundle bundle) throws Exception {
        final Object job = super.createJobInstance(bundle);
        beanFactory.autowireBean(job);
        return job;
    }
}
Secondly, override the default jobFactory in Spring's SchedulerFactoryBean.
<bean id="autoWireScheduler"  
      class="org.springframework.scheduling.quartz.SchedulerFactoryBean">  
     <property name="jobFactory" >  
       <bean class="com.geekspearls.quartz.example3.AutowiringSpringBeanJobFactory"/>  
     </property>  
     <property name="jobDetails">  
       <list>  
         <ref bean="injectJob2"/>  
       </list>  
     </property>  
     <property name="triggers">  
       <list>  
         <ref bean="simpleTrigger2"/>  
       </list>  
     </property>  
   </bean>
Then we can autowire any object into Quartz job class.
public class AnotherInjectTask extends QuartzJobBean {

    @Autowired
    private InjectObject injectObject;

    @Override
    protected void executeInternal(JobExecutionContext jobExecutionContext) throws JobExecutionException {
        System.out.println("[" + new Date() + "] I am saying another hello from a Quartz job, " +
                injectObject);
    }

    public void setInjectObject(InjectObject injectObject) {
        this.injectObject = injectObject;
    }
}
Be aware that in order to use the autowire annotation of Spring. Add either <context:annotation-config> or <context:componentscan> in the Spring context XML file. A completed example can be found on my GitHub Example3. Have a look at AnotherInjectTask and the Spring context XML.

In the example, if we run Example3 class as java application. We can see the following output in the console.
...
[Sun Aug 16 16:46:12 AEST 2015] I am saying hello from a Quartz job, GeeksPearls
[Sun Aug 16 16:46:12 AEST 2015] I am saying another hello from a Quartz job, null
[Sun Aug 16 16:46:12 AEST 2015] I am saying another hello from a Quartz job, GeeksPearls
...
The first line is output by the job using the Spring application context way. The second line is output by the job using the default Spring SchedulerFactoryBean. You can see the object is not injected so it outputs null. The third line is output by the job using our AutowiringSpringBeanJobFactory, you can see the object is injected successfully. Enjoy!

Sunday, August 9, 2015

Spring + Quartz integration example (2) - schedule jobs dynamically

Sometimes, we need schedule jobs dynamically. This requires us to use Quartz scheduler in a programming way rather than a static XML configuration way. I'll show in this post about how to do it with a simple example.


Environment

Java 8
Maven 3
Spring 3.2.3
Quartz 2.2.2
SFL4J 1.7.9 (to show Quartz start up information)


Scenario

We need schedule a report generation task for different departments in an organisation. The task is doing the same thing for different departments but needs to be run at different time, and it collects different data from database for different departments. Suppose sales department's report is to be generated at 7:00 am everyday, marketing department's report is to be generated at 8:00 am on Monday every week and engineering department's report is to be generated at 6:00 pm on the last Friday of every month.

It would be a little difficult to configure the tasks in Spring XML file, because it would be tricky to tell the XML file which department it is. Fortunately, Quartz allows us to use a programming way to schedule the task dynamically.


Implementation

The project configuration is as below.
   <dependencies>  
     <dependency>  
       <groupId>org.springframework</groupId>  
       <artifactId>spring-core</artifactId>  
       <version>${spring.version}</version>  
     </dependency>  
     <dependency>  
       <groupId>org.springframework</groupId>  
       <artifactId>spring-context-support</artifactId>  
       <version>${spring.version}</version>  
     </dependency>  
     <!-- Transaction dependency is required with Quartz integration -->  
     <dependency>  
       <groupId>org.springframework</groupId>  
       <artifactId>spring-tx</artifactId>  
       <version>${spring.version}</version>  
     </dependency>  
     <!-- Quartz framework -->  
     <dependency>  
       <groupId>org.quartz-scheduler</groupId>  
       <artifactId>quartz</artifactId>  
       <version>${quartz.version}</version>  
     </dependency>  
     <dependency>  
       <groupId>org.slf4j</groupId>  
       <artifactId>slf4j-api</artifactId>  
       <version>${slf4j.version}</version>  
     </dependency>  
     <dependency>  
       <groupId>org.slf4j</groupId>  
       <artifactId>slf4j-simple</artifactId>  
       <version>${slf4j.version}</version>  
     </dependency>  
   </dependencies>  
   <properties>  
     <spring.version>3.2.3.RELEASE</spring.version>  
     <quartz.version>2.2.1</quartz.version>  
     <slf4j.version>1.7.9</slf4j.version>  
   </properties>
To make it simple here, the task is just print out an information on the console. The task class is as below. the department name is retrieved from the JobDataMap and can be used in the report generation.
public class GenerateReportTask extends QuartzJobBean {

    public static final String DEPARTMENT = "DEPARTMENT";

    @Override
    protected void executeInternal(JobExecutionContext jobExecutionContext) throws JobExecutionException {
        JobDataMap dataMap = jobExecutionContext.getMergedJobDataMap();
        String department = dataMap.getString(DEPARTMENT);
        System.out.println("[" + new Date() + "] Generating report for department " + department);
    }
}
A QuartzScheduler class is used to schedule the task dynamically. The schedule CRON expressions are stored in a schedules map and the map is initialised in init() method. The init() method will be called when Spring initialise the QuartzScheduler bean.

public class QuartzScheduler {

    private Department[] departments = {Department.ENGINEER, Department.MARKETING, Department.SALES};
    private Map schedules = new HashMap();

    public void init() {
        schedules.put(Department.ENGINEER, "0 0 6 ? * 6L");
        schedules.put(Department.MARKETING, "0 0 8 ? * 2");
        schedules.put(Department.SALES, "0 0 7 * * ?");

        for (Department department : departments) {
            schedule(department);
        }
    }

    private enum Department {
        SALES, MARKETING, ENGINEER
    }
}
In the QuartzScheduler class, an instance of org.quartz.Scheduler class will be injected by Spring, it is the real Quartz scheduler to schedule the tasks. And the schedule() method is using Quartz's static method newJob() and newTrigger() to create the jobDetail and Trigger instances, then add the trigger to the scheduler. You might notice that we put the department name into the JobDataMap. As mentioned above, the department name will be used in the GenerateReportTask class.

public class QuartzScheduler {
    private Scheduler scheduler;    
    ...
    private void schedule(Department department) {
        JobDetail job = newJob(GenerateReportTask.class)
                .withIdentity(department.toString(), "reportgen")
                .build();
        job.getJobDataMap().put(GenerateReportTask.DEPARTMENT, department.toString());
        Trigger trigger = newTrigger()
                .withIdentity(department.toString(), "reportgen")
                .withSchedule(cronSchedule(schedules.get(department)))
                .forJob(job).build();
        try {
            scheduler.scheduleJob(job, trigger);
        } catch (SchedulerException e) {
            e.printStackTrace();
        }
    }
    ...
}
Finally, the Spring XML configuration file contains the bean definition of the QuartzScheduler class and the Spring SchedulerFactoryBean bean to create the real Quartz scheduler instance.
<beans xmlns="http://www.springframework.org/schema/beans"  
     xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"  
     xsi:schemaLocation="http://www.springframework.org/schema/beans http://www.springframework.org/schema/beans/spring-beans-3.2.xsd">  
   <bean id="quartzScheduler"  
      class="com.geekspearls.quartz.example2.QuartzScheduler"  
       init-method="init">  
     <property name="scheduler" ref="scheduler"/>  
   </bean>  
   <bean id="scheduler"  
      class="org.springframework.scheduling.quartz.SchedulerFactoryBean"/>  
 </beans>
And the Java application class to test our code.
public class Example2 {

    public static void main(String[] args) {
        ApplicationContext context = new ClassPathXmlApplicationContext("applicationContext-quartz2.xml");
        System.out.println("Application started [" + new Date() + "] ");
    }
}
A complete code can be found on my GitHub here. In order to demo the example, I put the schedules a much shorter period as below.
        schedules.put(Department.ENGINEER, "10 * * * * ?");
        schedules.put(Department.MARKETING, "30 * * * * ?");
        schedules.put(Department.SALES, "50 * * * * ?");
Run the Example2 class as a Java application and you can see the tasks are running at scheduled time on the console. I hope you enjoy it.

Saturday, July 25, 2015

Spring 3.2.3 + Quartz 2.2.1 integration example (1) - configuration in Spring context XML

Recently, I am assigned a task of integrating Quartz into a Spring project. I find it's quite an interesting job and would like to share some of my findings.

Quartz is a very popular scheduling library and is used in many Java applications to run jobs. It is open source, simple to use and most importantly, it is free. Here is the Quartz website Quartz Scheduler.

In this post, I'd share how to integrate Quartz into Spring. And how to schedule some simple jobs using Spring's JobDetailFactory and MethodInvokingJobDetailFactory in a simple trigger and CRON trigger respectively.

Environment

Java 8
Maven 3
Spring 3.2.3
Quartz 2.2.2
SFL4J 1.7.9 (to show Quartz start up information)

Project configuration

Create a new Maven project and add the following dependencies to the pom file (Assume Java 8 and Maven 3 have already been installed).
   <dependencies>  
     <dependency>  
       <groupId>org.springframework</groupId>  
       <artifactId>spring-core</artifactId>  
       <version>${spring.version}</version>  
     </dependency>  
     <dependency>  
       <groupId>org.springframework</groupId>  
       <artifactId>spring-context-support</artifactId>  
       <version>${spring.version}</version>  
     </dependency>  
     <!-- Transaction dependency is required with Quartz integration -->  
     <dependency>  
       <groupId>org.springframework</groupId>  
       <artifactId>spring-tx</artifactId>  
       <version>${spring.version}</version>  
     </dependency>  
     <!-- Quartz framework -->  
     <dependency>  
       <groupId>org.quartz-scheduler</groupId>  
       <artifactId>quartz</artifactId>  
       <version>${quartz.version}</version>  
     </dependency>  
     <dependency>  
       <groupId>org.slf4j</groupId>  
       <artifactId>slf4j-api</artifactId>  
       <version>${slf4j.version}</version>  
     </dependency>  
     <dependency>  
       <groupId>org.slf4j</groupId>  
       <artifactId>slf4j-simple</artifactId>  
       <version>${slf4j.version}</version>  
     </dependency>  
   </dependencies>  
   <properties>  
     <spring.version>3.2.3.RELEASE</spring.version>  
     <quartz.version>2.2.1</quartz.version>  
     <slf4j.version>1.7.9</slf4j.version>  
   </properties>

Quartz job and trigger configuration

The first job class simply print a greeting message. I print the date time at the beginning of the greeting so we can know when the job is triggered by Quartz.

public class HelloWorldTask {

    public void sayHello() {
        System.out.println("[" + new Date() + "] Hello from Quartz! World");
    }
}
Then let's schedule the job into Quartz. Firstly, we need configure the JobDetail bean in Spring context file. We'll use the MethodInvokingJobDetailFacrotyBean, it allows to specify which class and which method in the class to run when the job is triggered. For details about MethodInvokingJobDetailFacrotyBean, please read the Spring docs.

   <bean id="helloWorldTask" class="com.geekspearls.quartz.task.HelloWorldTask"/>
   
   <bean id="helloWorldJob"  
      class = "org.springframework.scheduling.quartz.MethodInvokingJobDetailFactoryBean">  
     <property name="targetObject" ref="helloWorldTask"/>  
     <property name="targetMethod" value="sayHello"/>  
   </bean>

Secondly, we need to add our job to a trigger. We will use the SimpleTriggerFactoryBean to schedule our first job and set the job to be run every 5 seconds and delay 1 second to start. For details about SimpleTriggerFactoryBean, please read the Spring docs.

  <bean id="simpleTrigger"  
      class="org.springframework.scheduling.quartz.SimpleTriggerFactoryBean">  
     <property name="jobDetail" ref="helloWorldJob" />  
     <property name="repeatInterval" value="5000" />  
     <property name="startDelay" value="1000" />  
   </bean>  

Then let's create our second job. The second job class extends QuartzJobBean interface. When it is triggered, executeInternal method will be invoked. Inside the method, it takes the value of 'name' from JobDataMap which we set in the jobDetails configuration and print a greeting message. The date time will also be printed out so we can know when the job is triggered.

public class SayHelloTask extends QuartzJobBean {
    @Override
    protected void executeInternal(JobExecutionContext jobExecutionContext) throws JobExecutionException {
        String name = jobExecutionContext.getMergedJobDataMap().getString("name");
        System.out.println("[" + new Date() + "] Hello from Quartz! " + name);
    }
}

For our second job, we will use the JobDetailFactoryBean to configure it in Spring context file and pass in a value of 'name' into jobDataMap.
  <bean id="sayHelloJob"  
      class="org.springframework.scheduling.quartz.JobDetailFactoryBean">  
     <property name="jobClass" value="com.geekspearls.quartz.task.SayHelloTask"/>  
     <property name="jobDataAsMap">  
       <map>  
         <entry key="name" value="Geek's pearls reader"/>  
       </map>  
     </property>  
     <property name="durability" value="true"/>  
   </bean> 

Then we schedule this job with CronTriggerFactoryBean. It is scheduled to run every 10 seconds start from every 0 second. For details about CRON, please read Quartz CronTrigger Tutorial
  <bean id="cronTrigger"  
      class="org.springframework.scheduling.quartz.CronTriggerFactoryBean">  
     <property name="jobDetail" ref="sayHelloJob" />  
     <property name="cronExpression" value="0/10 * * * * ?"/>  
   </bean> 

Now, we have our jobs and triggers ready. Let's add them into Quartz scheduler.
   <bean class="org.springframework.scheduling.quartz.SchedulerFactoryBean">  
     <property name="jobDetails">  
       <list>  
         <ref bean="helloWorldJob" />  
         <ref bean="sayHelloJob" />  
       </list>  
     </property>  
     <property name="triggers">  
       <list>  
         <ref bean="simpleTrigger" />  
         <ref bean="cronTrigger" />  
       </list>  
     </property>  
   </bean>

Finally, everything is ready. The completed Spring context XML file is below.
   <beans xmlns="http://www.springframework.org/schema/beans"  
     xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"  
     xsi:schemaLocation="http://www.springframework.org/schema/beans http://www.springframework.org/schema/beans/spring-beans-3.2.xsd">  
   <bean id="sayHelloJob"  
      class="org.springframework.scheduling.quartz.JobDetailFactoryBean">  
     <property name="jobClass" value="com.geekspearls.quartz.task.SayHelloTask"/>  
     <property name="jobDataAsMap">  
       <map>  
         <entry key="name" value="Geek's pearls reader"/>  
       </map>  
     </property>  
     <property name="durability" value="true"/>  
   </bean>  
   <bean id="helloWorldTask" class="com.geekspearls.quartz.task.HelloWorldTask"/>  
   <bean id="helloWorldJob"  
      class = "org.springframework.scheduling.quartz.MethodInvokingJobDetailFactoryBean">  
     <property name="targetObject" ref="helloWorldTask"/>  
     <property name="targetMethod" value="sayHello"/>  
   </bean>  
   <bean id="simpleTrigger"  
      class="org.springframework.scheduling.quartz.SimpleTriggerFactoryBean">  
     <property name="jobDetail" ref="helloWorldJob" />  
     <property name="repeatInterval" value="5000" />  
     <property name="startDelay" value="1000" />  
   </bean>  
   <bean id="cronTrigger"  
      class="org.springframework.scheduling.quartz.CronTriggerFactoryBean">  
     <property name="jobDetail" ref="sayHelloJob" />  
     <property name="cronExpression" value="0/10 * * * * ?"/>  
   </bean>  
   <bean class="org.springframework.scheduling.quartz.SchedulerFactoryBean">  
     <property name="jobDetails">  
       <list>  
         <ref bean="helloWorldJob" />  
         <ref bean="sayHelloJob" />  
       </list>  
     </property>  
     <property name="triggers">  
       <list>  
         <ref bean="simpleTrigger" />  
         <ref bean="cronTrigger" />  
       </list>  
     </property>  
   </bean>  
 </beans>

Now, let's test it! Run the following class as Java application.
public class HelloWorld {
    public static void main(String[] args) {
        ApplicationContext context = new ClassPathXmlApplicationContext("applicationContext.xml");
        System.out.println("Application started [" + new Date() + "]");
    }
}

In the log and console output, we can see the information below. Firstly, it tells us a Quartz scheduler with instanceId 'NON_CLUSTER' running locally with 10 threads. And it doesn't support persistence and cluster. I will share how to use clustered Quartz scheduler in my next post.
[main] INFO org.quartz.core.QuartzScheduler - Scheduler meta-data: Quartz Scheduler (v2.2.1) 'org.springframework.scheduling.quartz.SchedulerFactoryBean#0' with instanceId 'NON_CLUSTERED'
  Scheduler class: 'org.quartz.core.QuartzScheduler' - running locally.
  NOT STARTED.
  Currently in standby mode.
  Number of jobs executed: 0
  Using thread pool 'org.quartz.simpl.SimpleThreadPool' - with 10 threads.
  Using job-store 'org.quartz.simpl.RAMJobStore' - which does not support persistence. and is not clustered.

Then we can see the application is started at 17:14:23. 1 second later, our first job is triggered and repeated every 5 seconds. At 17:14:30, our second job is triggered and repeated every 10 seconds. That's what we expected! The completed example can be found on my GitHub here. I hope you will enjoy it!
Application started [Sat Jul 25 17:14:23 AEST 2015]
[Sat Jul 25 17:14:24 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:14:29 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:14:30 AEST 2015] Hello from Quartz! Geek's pearls reader
[Sat Jul 25 17:14:34 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:14:39 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:14:40 AEST 2015] Hello from Quartz! Geek's pearls reader
[Sat Jul 25 17:14:44 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:14:49 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:14:50 AEST 2015] Hello from Quartz! Geek's pearls reader
[Sat Jul 25 17:14:54 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:14:59 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:00 AEST 2015] Hello from Quartz! Geek's pearls reader
[Sat Jul 25 17:15:04 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:09 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:10 AEST 2015] Hello from Quartz! Geek's pearls reader
[Sat Jul 25 17:15:14 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:19 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:20 AEST 2015] Hello from Quartz! Geek's pearls reader
[Sat Jul 25 17:15:24 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:29 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:30 AEST 2015] Hello from Quartz! Geek's pearls reader
[Sat Jul 25 17:15:34 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:39 AEST 2015] Hello from Quartz! World
[Sat Jul 25 17:15:40 AEST 2015] Hello from Quartz! Geek's pearls reader
...

Monday, June 29, 2015

Git with Eclipse (4) - pushing local repositories to remote repositories

This post describes how to create a remote repository at GitHub and how to push a local repository to remote repository at GitHub using EGit.


Create a repository at GitHub

Firstly, we need a remote repository to start. I will use GitHub to host our remote repository. Sign up from here to get an account at GitHub. After sign in, click the  icon and select New repository.
In the next screen, give a name "HelloWorld" to our repository. You can also write a brief description about the repository, so other people will know what is your repository about. Choose Public as the repository type, so it can be accessed by anyone with restriction on modification. Private repository is available to paid users. If you tick Initialize this repository with a README, GitHub will create a read me file in the repository. We leave it as it is so we will have a clean repository. Then click the Create repository button and our HelloWorld repository is created.

In the next screen, you can see the HelloWorld repository is empty and GitHub provides several suggestions to start with. We will leave it for now and go back to HelloWold project in Eclipse.

SSH configuration

If you are going to use SSH protocol instead of HTTP for read and write access to the remote repository at GitHub, you have to configure the SSH key in Eclipse and GitHub.

Eclipse SSH configuration

Open Eclipse Preferences via Windows -> Preferences. Then go to General -> Network Connections -> SSH2. Select Key Management tab and click the Generate RSA Key... button. Eclipse will generate a public key (Copy the public key to a text file and it will be uploaded to GitHub later). Then enter a pass phrase in Passphrase: and Confirm passphrase: fields, it will be used to protect the private key. Click the Save Private Key... button to save the private key in your computer (usually it is saved in C:\Users\<username>\.ssh). Then go to General tab and enter the path of the private key (usually is C:\Users\<username>\.ssh) in SSH2 home: field. Click Apply button to save the configuration.

GitHub SSH configuration

Log in to GitHub. Then click the icon on the top right of the screen and select Settings in the menu. Choose SSH Keys in the navigator on the left. Then click Add SSH Key button and paste the Eclipse generated public key into the Key text box. Title field is optional.

Click Add key button and you will be asked to confirm your password. After the password is confirmed, the public key is added to GitHub. Now you are able to use SSH protocol to access your repositories at GitHub.

Push the local repository to remote repository

Firstly, we need a local repository to push. Create the HelloWorld project in Eclipse and share it in a local Git repository. Please refer to Git with Eclipse (3) - basic use cases in EGit with local repository for how to share project in local repository.

Secondly, because we created an empty repository at GitHub in previous step, we need to create a branch in the remote repository. Open Git perspective in Eclipse by selecting Windows -> Open Perspective -> Other....in the menu, then choose Git in the opened dialog.

In the Git perspective, expand HelloWorld repository, right click on Remotes and select Create Remote... In the menu.

Give a remote name in the opened dialog (Usually is origin by default) and select Configure push, then click OK.


The Configure Push dialog asks for the URI of the remote repository. we can copy the URI from HelloWorld repository at GitHub (we will use SSH URI in our example). Log in to GitHub and open HelloWorld repository. In the top section of the page, click on SSH and click theicon to copy the SSH URI.

Then go back to Eclipse. Click the Change... button in Configure Push dialog and paste the SSH URI into the URI: field in the opened Destination Git Repository dialog. Select ssh in the Protocol: field. Authentication Users: is git. Leave the rest as what it is and click Finish. You will be asked for the pass phrase. Enter the pass phrase you have set up in the SSH configuration and click OK.

Then click Save and Push button in Configure Push dialog.


A confirmation window will be shown once the repository is pushed to GitHub successfully.

Click OK to close the window. Log in to GitHub and open HelloWorld repository. You will see the HelloWorld project is now available at GitHub.

Now the HelloWorld project is ready to be forked or collaborated by other contributors. Also, you can fetch any updates in the HelloWorld project from GitHub and push your changes in HelloWorld project to GitHub. For how to clone a remote repository and fetch/push changes. Please read Git with Eclipse (5) - work with remote repositories (coming soon...).


Reference: